Replace std::shared_ptr<Node> with c10::intrusive_ptr<Node> throughout the autograd system. Node now inherits from c10::intrusive_ptr_target instead of std::enable_shared_from_this<Node>.

**BC Breaking**:

This changes the signature of `Tensor::grad_fn`.  Accesses to `Tensor.grad_fn()` should change from `std::shared_ptr<Node>` to `c10::intrusive_ptr<Node>`. Similarly, construction of a C++ autograd function should change from:

```c++
std::shared_ptr<CustomCppNode> node(new CustomCppNode(), torch::autograd::deleteNode);
```

to

```c++
auto node = c10::make_intrusive<CustomCppNode>();
```

Authored with Claude.

Pull Request resolved: https://github.com/pytorch/pytorch/pull/181139
Approved by: https://github.com/albanD
This PR updates the error message in autograd when an input tensor does not set to `require_grad`. The original message does not contain the index info, making users hard to debug.
The error message style consists with that on line 105-109.
Co-authored-by: Jeffrey Wan <soulitzer@gmail.com>
Pull Request resolved: https://github.com/pytorch/pytorch/pull/123154
Approved by: https://github.com/soulitzer
When the hook registered by Tensor::register_hook (in C++) gets passed
an undefined tensor, it raises an internal assert in debug mode.
The cause is that we attempt to construct an OptionalTensorRef
(https://github.com/pytorch/pytorch/blob/4448c78a5d8ce91573fb8779355838bc78bfea33/aten/src/ATen/core/Tensor.h#L68)
which asserts that the passed-in TensorBase is defined.

The fix is that we create a new TensorRef class to convert the
TensorBase into a Tensor without bumping the refcount (which is what
OptionalTensorRef does). We cannot reuse OptionalTensorRef because
OptionalTensorRef represents `optional<Tensor>` that cannot hold an
Undefined Tensor.

For some more historical context, it looks like this behavior was introduced
in #63612

Test Plan:
- new tests
Pull Request resolved: https://github.com/pytorch/pytorch/pull/105587
Approved by: https://github.com/soulitzer
Fixes https://github.com/pytorch/pytorch/issues/96887

We error out in BOTH the case when graph is created and when it is not created.

Still bc-breaking, but not as severe because we are limiting to the case where someone uses setup_context.

This makes setup_context and non-setup_context versions diverge in their behavior
- With the non-setup_context version, saved variables are assumed to have the grad_fn of the inputs.
- But now with the setup_context version, we produce an error for this case.

Pull Request resolved: https://github.com/pytorch/pytorch/pull/97212
Approved by: https://github.com/zou3519
### Introduction
<!-- What did you change and why was it needed? -->

Removing unnecessary weight gradient calculation is very important for applications that need high-order derivatives during training. However, this is not supported by the current Autograd engine.

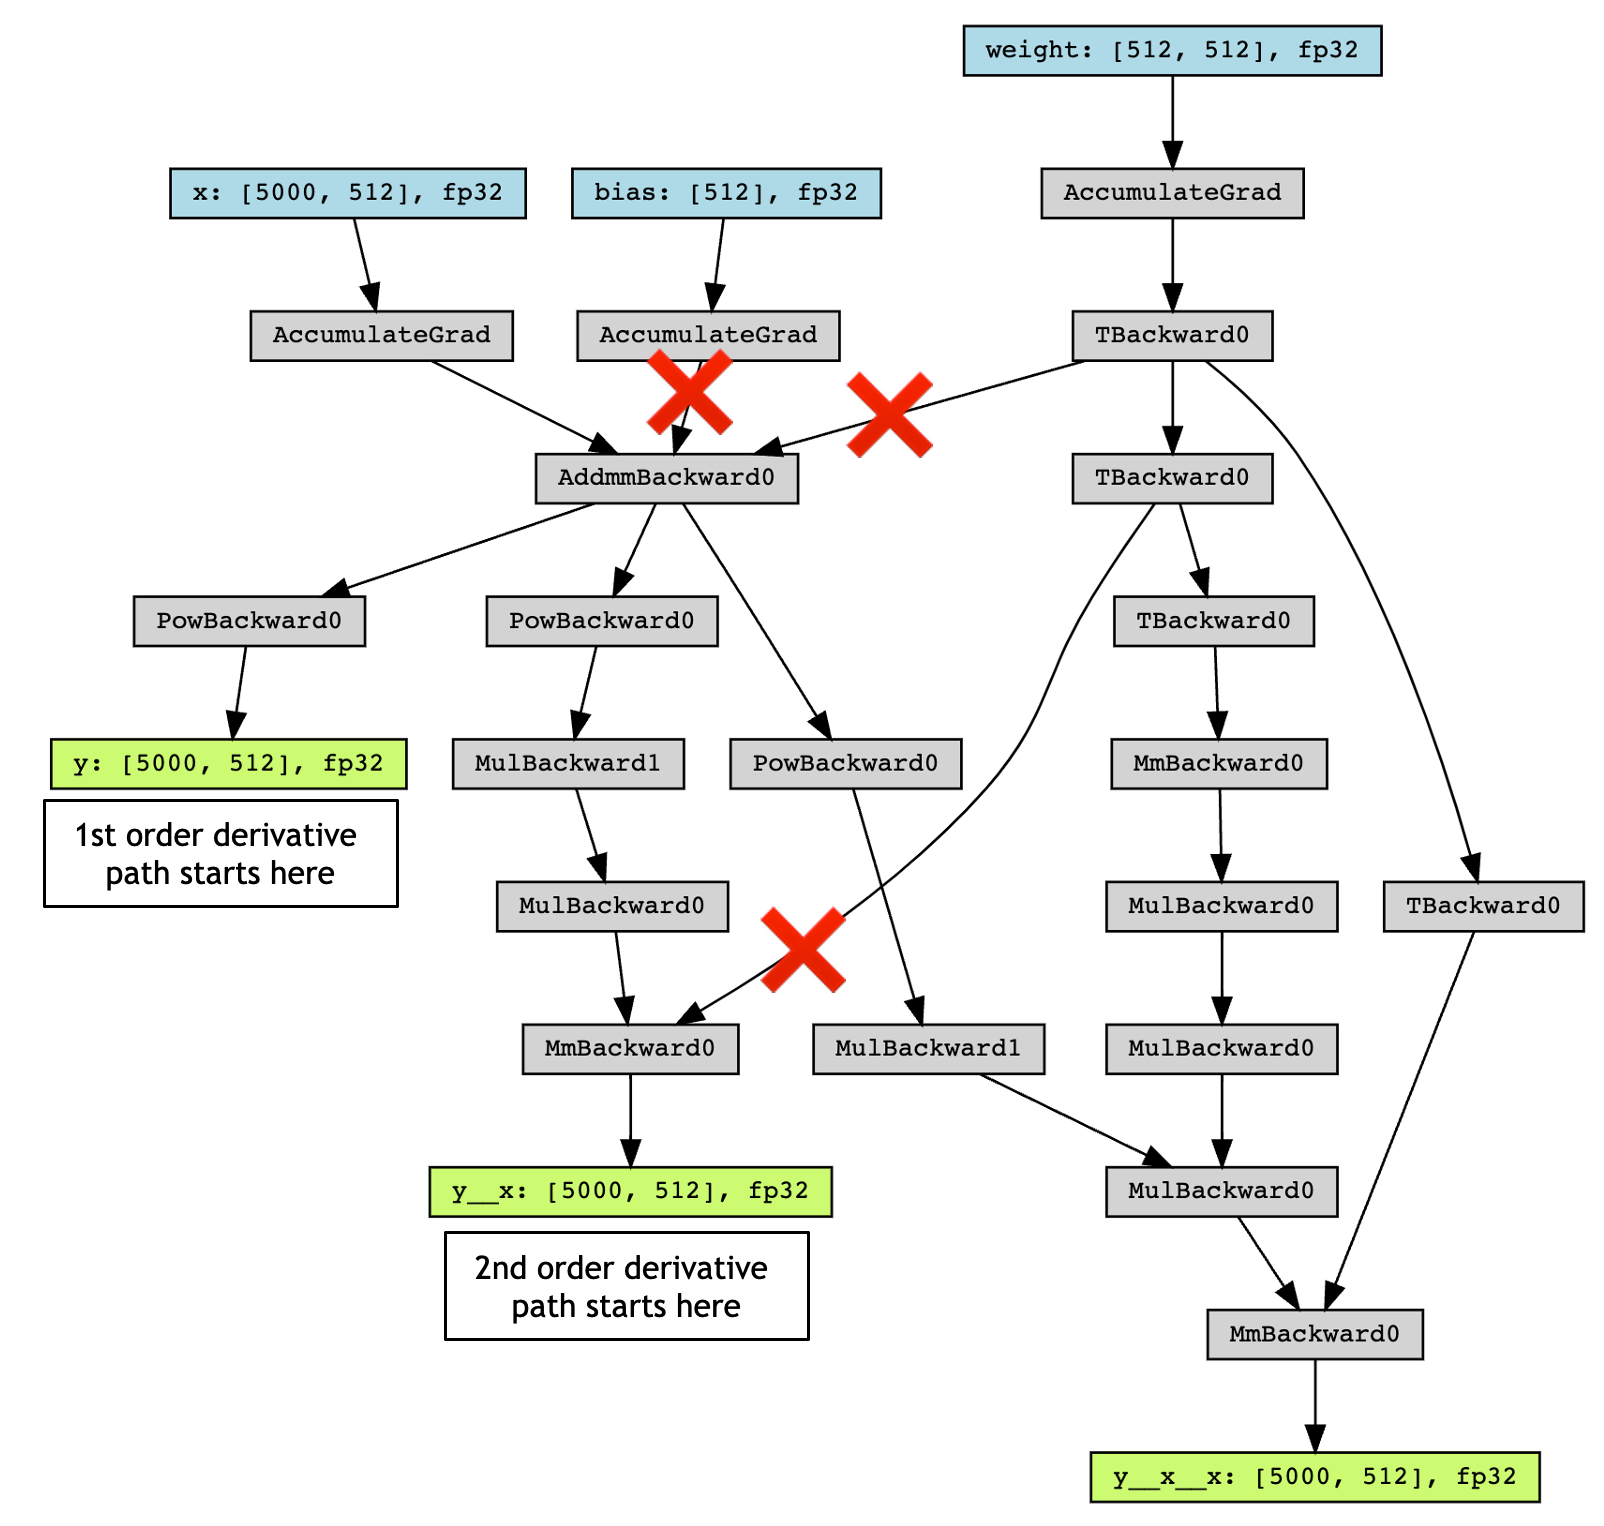
For more detail: The backward function of a `matmul` operator (e.g., `linear` `addmm` `mm`), has two matmuls, one for `input gradient` and another for `weight gradient`. For a typical neural network (nn) with a few linear layers and activation functions, if the user calls `torch.autograd.grad()` to calculate the derivative of the nn output `y` w.r.t the nn input `x`,  only the `input gradient` of the `matmul` operator is needed, and the `weight gradient` is discarded. However, the current PyTorch autograd engine will always calculate the `weight gradient` if `weight` requires gradient (the calculation of the high-order derivative is performed during training).

The figure attached shows the autograd graph of the following code snippet:
```py
y = torch.nn.functional.linear(x, weight, bias)
y = y.pow(2)
# first order derivative
y__x, = torch.autograd.grad(y, x, grad_outputs=grad_outputs, create_graph=True)
# first order derivative
y__x__x, = torch.autograd.grad(y__x, x, grad_outputs=grad_outputs, create_graph=True)
```
The path with ❌ is not needed when calculating derivatives.

<img width="50%" alt="image" src="https://user-images.githubusercontent.com/9999318/182018117-719c5a23-bcc6-4a63-8e8d-1bca3ebda2e3.png">

### Issue
<!-- Link to Issue ticket or RFP -->
Related issue: https://github.com/pytorch/pytorch/issues/56500

### Method
When calling `torch.autograd.grad`, `exec_info_` is created for each GraphTask, which allows filtering paths on the graph that are not needed. However, when the GraphTask calls into the node, the node still does not know whether the edges are needed or not. In the case of matmul, `weight.requires_grad is True` so the weight gradient is always calculated.

Following https://github.com/pytorch/pytorch/issues/56500#issuecomment-825694656, this PR passes the graph task's thread_local `exec_info_` into the node, so it could trim unnecessary edges during `torch.autograd.grad` calls.

### Benchmark
Benchmark script: https://gist.github.com/yueyericardo/24158433a2021c51eeef9c3e2722df99

Benchmark result:
6 hidden layers, batch size 10000, on A100

FP32 result
| hessian benchmark             | FP32 (before) | FP32 (After)      | FP32 (Functorch v0.1.1) |
| ----------------------------- | ------------- | ----------------- | ----------------------- |
| Linear + ReLU (no backward)   | 55.658 ms     | 29.392 ms (1.90X) | 29.547 ms (1.90X)       |
| Linear + ReLU (with backward) | 81.173 ms     | 54.917 ms (1.47X) | 68.988 ms (1.18X)       |

TF32 result
| hessian benchmark             | TF32 (before) | TF32 (after)      | TF32 (Functorch v0.1.1) |
| ----------------------------- | ------------- | ----------------- | ----------------------- |
| Linear + ReLU (no backward)   | 19.801 ms     | 11.259 ms (1.76X) | 10.754 ms (1.84X)       |
| Linear + ReLU (with backward) | 29.167 ms     | 20.466 ms (1.42X) | 22.784 ms (1.28X)       |

For FP32 result, we could get 1.9X speed up for hessian calculation, and 1.47X speed up during training, which is even faster than functorch `vmap(jacfwd(jacrev` implementation. (functorch has performance regression on v0.2.0, https://github.com/pytorch/functorch/issues/989, so we are using v0.1.1 for benchmark)

@zou3519 does functorch also includes similar optimizations during hessian calculation? If not, what do we need to do so the functorch could also benefit from this PR?

### Testing
<!-- How did you test your change? -->

- [x] we need to figure out a way for unittest

### Thanks
Thanks for the great blog: [How Computational Graphs are Executed in PyTorch | PyTorch](https://pytorch.org/blog/how-computational-graphs-are-executed-in-pytorch/)

cc @zasdfgbnm @albanD
Pull Request resolved: https://github.com/pytorch/pytorch/pull/82544
Approved by: https://github.com/soulitzer
See this doc: https://docs.google.com/document/d/1KiRdnoj6B4cI3yl017hTbCqcOGO1gWIpUf20sldipHM/edit#

Two issues (1) regarding hooks in general and (2) regarding retains grad hooks are fixed, Python hooks, which rely on a different mechanism are not discussed here:
- Hooks in cpp in general
  - (fixed) new hooks to registered to a newer version of the tensor no longer get applied to grad_fn
    associated with older version of the tensor when the first hook was ever registered
  - (unchanged) hooks registered to the older version of the tensor remain active on
- Retains grad hooks
  - (fixed) now get moved to the latest grad_fn. NB: To the user, retains_grad is not considered hooks
    or expected to behave like hooks (which we consider properties of the grad_fn) vs retains_gradness
    which is a property of the tensor.
- (not in this PR) Python hooks
  - (will fix) same issue as hooks in cpp where new hooks are being applied to grad_fn associated
    with the older version of the tensor
Pull Request resolved: https://github.com/pytorch/pytorch/pull/79996
Approved by: https://github.com/albanD
Summary:
Pull Request resolved: https://github.com/pytorch/pytorch/pull/67195

Now that `is_nonzero` is part of `at::native` refer https://github.com/pytorch/pytorch/pull/66663, replacing `TensorCompare::is_nonzero` to `at::native::is_nonzero`

ghstack-source-id: 141514416

Test Plan: CI

Reviewed By: larryliu0820

Differential Revision: D31704041

fbshipit-source-id: 36813e5411d0aa2eb2d0442e2a195bbed417b33d
Summary:
Pull Request resolved: https://github.com/pytorch/pytorch/pull/63878

See https://github.com/pytorch/pytorch/issues/64407, https://github.com/pytorch/pytorch/issues/62032 for context:

In this PR:
 - Add boxed kernel by replicating `gen_inplace_or_view`'s logic that is ONLY for use with the Autograd not-implemented kernel
   - Unlike `gen_inplace_or_view` we always pass a view_func to as_view in order to ensure that an "derivative is not implemented" error is raised even if an in-place update is performed on the view. Without the `view_func`, the CopySlice + AsStridedBackward nodes would replace the NotImplemented node.
   - This limitation makes it impossible to use this node for general use
   - view relationship must be between first input (must be tensor) and first output (may be tensor or vec of tensor)
   - do not support non-differentiable views (_values, _indices, view.dtype) - view relationship is always fw and bw differentiable
 - Adds the macro `#define REGISTER_AUTOGRAD_NOT_IMPLEMENTED_FALLBACK(ns, op)` to be the interface for this feature:
   - static initialization can be slowed down(? not measured) if there are many registrations, because each line translates to 2 library calls but the workaround is just to manually use the two functions `AutogradNotImplementedFallback` and `ADInplaceOrViewFallback` and call `m.impl`.
 - Adds testing:
    - for views: view relationship created
      -  performing in-place operation on the view, raises properly
      - trying to create two view relationships is not allowed,
      - single view relationship but not first input/first output should error
      - view relation created properly for tensor vector output
    - for in-place:
      - version count bump
      - triggers rebase_history
      - multiple mutations is okay and also updates version counter
 - TODO (follow up): Update tutorials for adding  third-party operators (and document the above limitations)
 - TODO (follow up): Look at torch-audio/torch-vision and identify places where this can simplify existing code

EDIT: Made it more clear what is introduced in this PR and moved some more contextual stuff into the issue itself

Test Plan: Imported from OSS

Reviewed By: albanD

Differential Revision: D30901714

Pulled By: soulitzer

fbshipit-source-id: 48de14c28be023ff4bd31b7ea5e7cba88aeee04c
Summary:
As GoogleTest `TEST` macro is non-compliant with it as well as `DEFINE_DISPATCH`

All changes but the ones to `.clang-tidy` are generated using following script:
```
for i in `find . -type f -iname "*.c*" -or -iname "*.h"|xargs grep cppcoreguidelines-avoid-non-const-global-variables|cut -f1 -d:|sort|uniq`;  do sed -i "/\/\/ NOLINTNEXTLINE(cppcoreguidelines-avoid-non-const-global-variables)/d" $i; done
```

Pull Request resolved: https://github.com/pytorch/pytorch/pull/62008

Reviewed By: driazati, r-barnes

Differential Revision: D29838584

Pulled By: malfet

fbshipit-source-id: 1b2f8602c945bd4ce50a9bfdd204755556e31d13
Summary:
The grad() function needs to return the updated values, and hence
needs a non-empty inputs to populate.

Pull Request resolved: https://github.com/pytorch/pytorch/pull/52016

Test Plan:
Passes Python and C++ unit tests, and added new tests to catch this behavior.

Fixes https://github.com/pytorch/pytorch/issues/47061

Reviewed By: albanD

Differential Revision: D26406444

Pulled By: dagitses

fbshipit-source-id: 023aeca9a40cd765c5bad6a1a2f8767a33b75a1a
Summary:
Fixes https://github.com/pytorch/pytorch/issues/35379

 - Adds  `retains_grad` attribute backed by cpp as a native function. The python bindings for the function are skipped to be consistent with `is_leaf`.
   - Tried writing it without native function, but the jit test `test_tensor_properties` seems to require that it be a native function (or alternatively maybe it could also work if we manually add a prim implementation?).
 - Python API now uses `retain_grad` implementation from cpp

Pull Request resolved: https://github.com/pytorch/pytorch/pull/59362

Reviewed By: jbschlosser

Differential Revision: D28969298

Pulled By: soulitzer

fbshipit-source-id: 335f2be50b9fb870cd35dc72f7dadd6c8666cc02
Summary:
Fixes https://github.com/pytorch/pytorch/issues/4661
- Add warnings in engine's `execute` function so it can be triggered through both cpp and python codepaths
- Adds an RAII guard version of `c10::Warning::set_warnAlways` and replaces all prior usages of the set_warnAlways with the new one

Pull Request resolved: https://github.com/pytorch/pytorch/pull/59412

Reviewed By: jbschlosser

Differential Revision: D28969294

Pulled By: soulitzer

fbshipit-source-id: b03369c926a3be18ce1cf363b39edd82a14245f0
Summary:
This is an automatic change generated by the following script:
```
#!/usr/bin/env python3
from subprocess import check_output, check_call
import os

def get_compiled_files_list():
    import json
    with open("build/compile_commands.json") as f:
        data = json.load(f)
    files = [os.path.relpath(node['file']) for node in data]
    for idx, fname in enumerate(files):
        if fname.startswith('build/') and fname.endswith('.DEFAULT.cpp'):
            files[idx] = fname[len('build/'):-len('.DEFAULT.cpp')]
    return files

def run_clang_tidy(fname):
    check_call(["python3", "tools/clang_tidy.py", "-c", "build", "-x", fname,"-s"])
    changes = check_output(["git", "ls-files", "-m"])
    if len(changes) == 0:
        return
    check_call(["git", "commit","--all", "-m", f"NOLINT stubs for {fname}"])

def main():
    git_files = check_output(["git", "ls-files"]).decode("ascii").split("\n")
    compiled_files = get_compiled_files_list()
    for idx, fname in enumerate(git_files):
        if fname not in compiled_files:
            continue
        if fname.startswith("caffe2/contrib/aten/"):
            continue
        print(f"[{idx}/{len(git_files)}] Processing {fname}")
        run_clang_tidy(fname)

if __name__ == "__main__":
    main()
```

Pull Request resolved: https://github.com/pytorch/pytorch/pull/56892

Reviewed By: H-Huang

Differential Revision: D27991944

Pulled By: malfet

fbshipit-source-id: 5415e1eb2c1b34319a4f03024bfaa087007d7179
Summary:
Fixes https://github.com/pytorch/pytorch/issues/39784
At the time the issue was filed, there was only issue (1) below.

There are actually now two issues here:
1. We always set all inputs passed in through `inputs` arg as `needed = True` in exec_info. So if we pass in an input that has a grad_fn that is not materialized, we create an entry of exec_info with nullptr as key with `needed = True`. Coincidentally, when we perform simple arithmetic operations, such as "2 * x", one of the next edges of mul is an invalid edge, meaning that its grad_fn is also nullptr. This causes the discovery algorithm to set all grad_fns that have a path to this invalid_edge as `needed = True`.
2. Before the commit that enabled the engine skipped the dummy node, we knew that root node is always needed, i.e., we hardcode `exec_info[&graph_root]=true`. The issue was that this logic wasn't updated after the code was updated to skip the graph root.

To address (1), instead of passing in an invalid edge if an input in `inputs` has no grad_fn, we create a dummy grad_fn. This is done in both python and cpp entry points. The alternative is to add logic for both backward() and grad() cases to check whether the grad_fn is nullptr and set needed=false in that case (the .grad() case would be slightly more complicated than the .backward() case here).

For (2), we perform one final iteration of the discovery algorithm so that we really know whether we need to execute the graph root.

Pull Request resolved: https://github.com/pytorch/pytorch/pull/51940

Reviewed By: VitalyFedyunin

Differential Revision: D26369529

Pulled By: soulitzer

fbshipit-source-id: 14a01ae7988a8de621b967a31564ce1d7a00084e
Summary:
Clear static variable at the end of the test to ensure test passes after re-runs

Pull Request resolved: https://github.com/pytorch/pytorch/pull/49581

Test Plan:
`./bin/test_api "--gtest_filter=CustomAutogradTest.ReentrantPriority" --gtest_repeat=50`
Before the change all subsequent runs of the test failed with
```
../test/cpp/api/autograd.cpp:681: Failure
Expected equality of these values:
  order.size()
    Which is: 310
  10
```

Reviewed By: mrshenli

Differential Revision: D25632374

Pulled By: malfet

fbshipit-source-id: 4814d22b5dff15e1b38a0187e51070771fd58370
Summary:
This is a followup to the C++ anomaly detection mode, implementing the guard.

Pull Request resolved: https://github.com/pytorch/pytorch/pull/47164

Reviewed By: mruberry

Differential Revision: D24682574

Pulled By: albanD

fbshipit-source-id: b2224a56bf6eca0b90b8e10ec049cbcd5af9d108
Summary:
Fixes https://github.com/pytorch/pytorch/issues/46373

As noted in https://github.com/pytorch/pytorch/issues/46373, there needs to be a flag passed into the engine that indicates whether it was executed through the backward api or grad api. Tentatively named the flag `accumulate_grad` since functionally, backward api accumulates grad into .grad while grad api captures the grad and returns it.

Moving changes not necessary to the python api (cpp, torchscript) to a new PR.

Pull Request resolved: https://github.com/pytorch/pytorch/pull/46855

Reviewed By: ngimel

Differential Revision: D24649054

Pulled By: soulitzer

fbshipit-source-id: 6925d5a67d583eeb781fc7cfaec807c410e1fc65
 Sam Gross